Cernity Vantage: from a finding to a defensible investigation
Findings export to your SIEM, but analysts work in Cernity Vantage — the native, queue-centric console where a lead becomes an investigation and an investigation becomes a disposition that tunes the pipeline. A detector gives you a lead. Vantage is where you establish what happened, how reliable the evidence is, whether the activity was authorized, and what action is justified.
The investigation queue
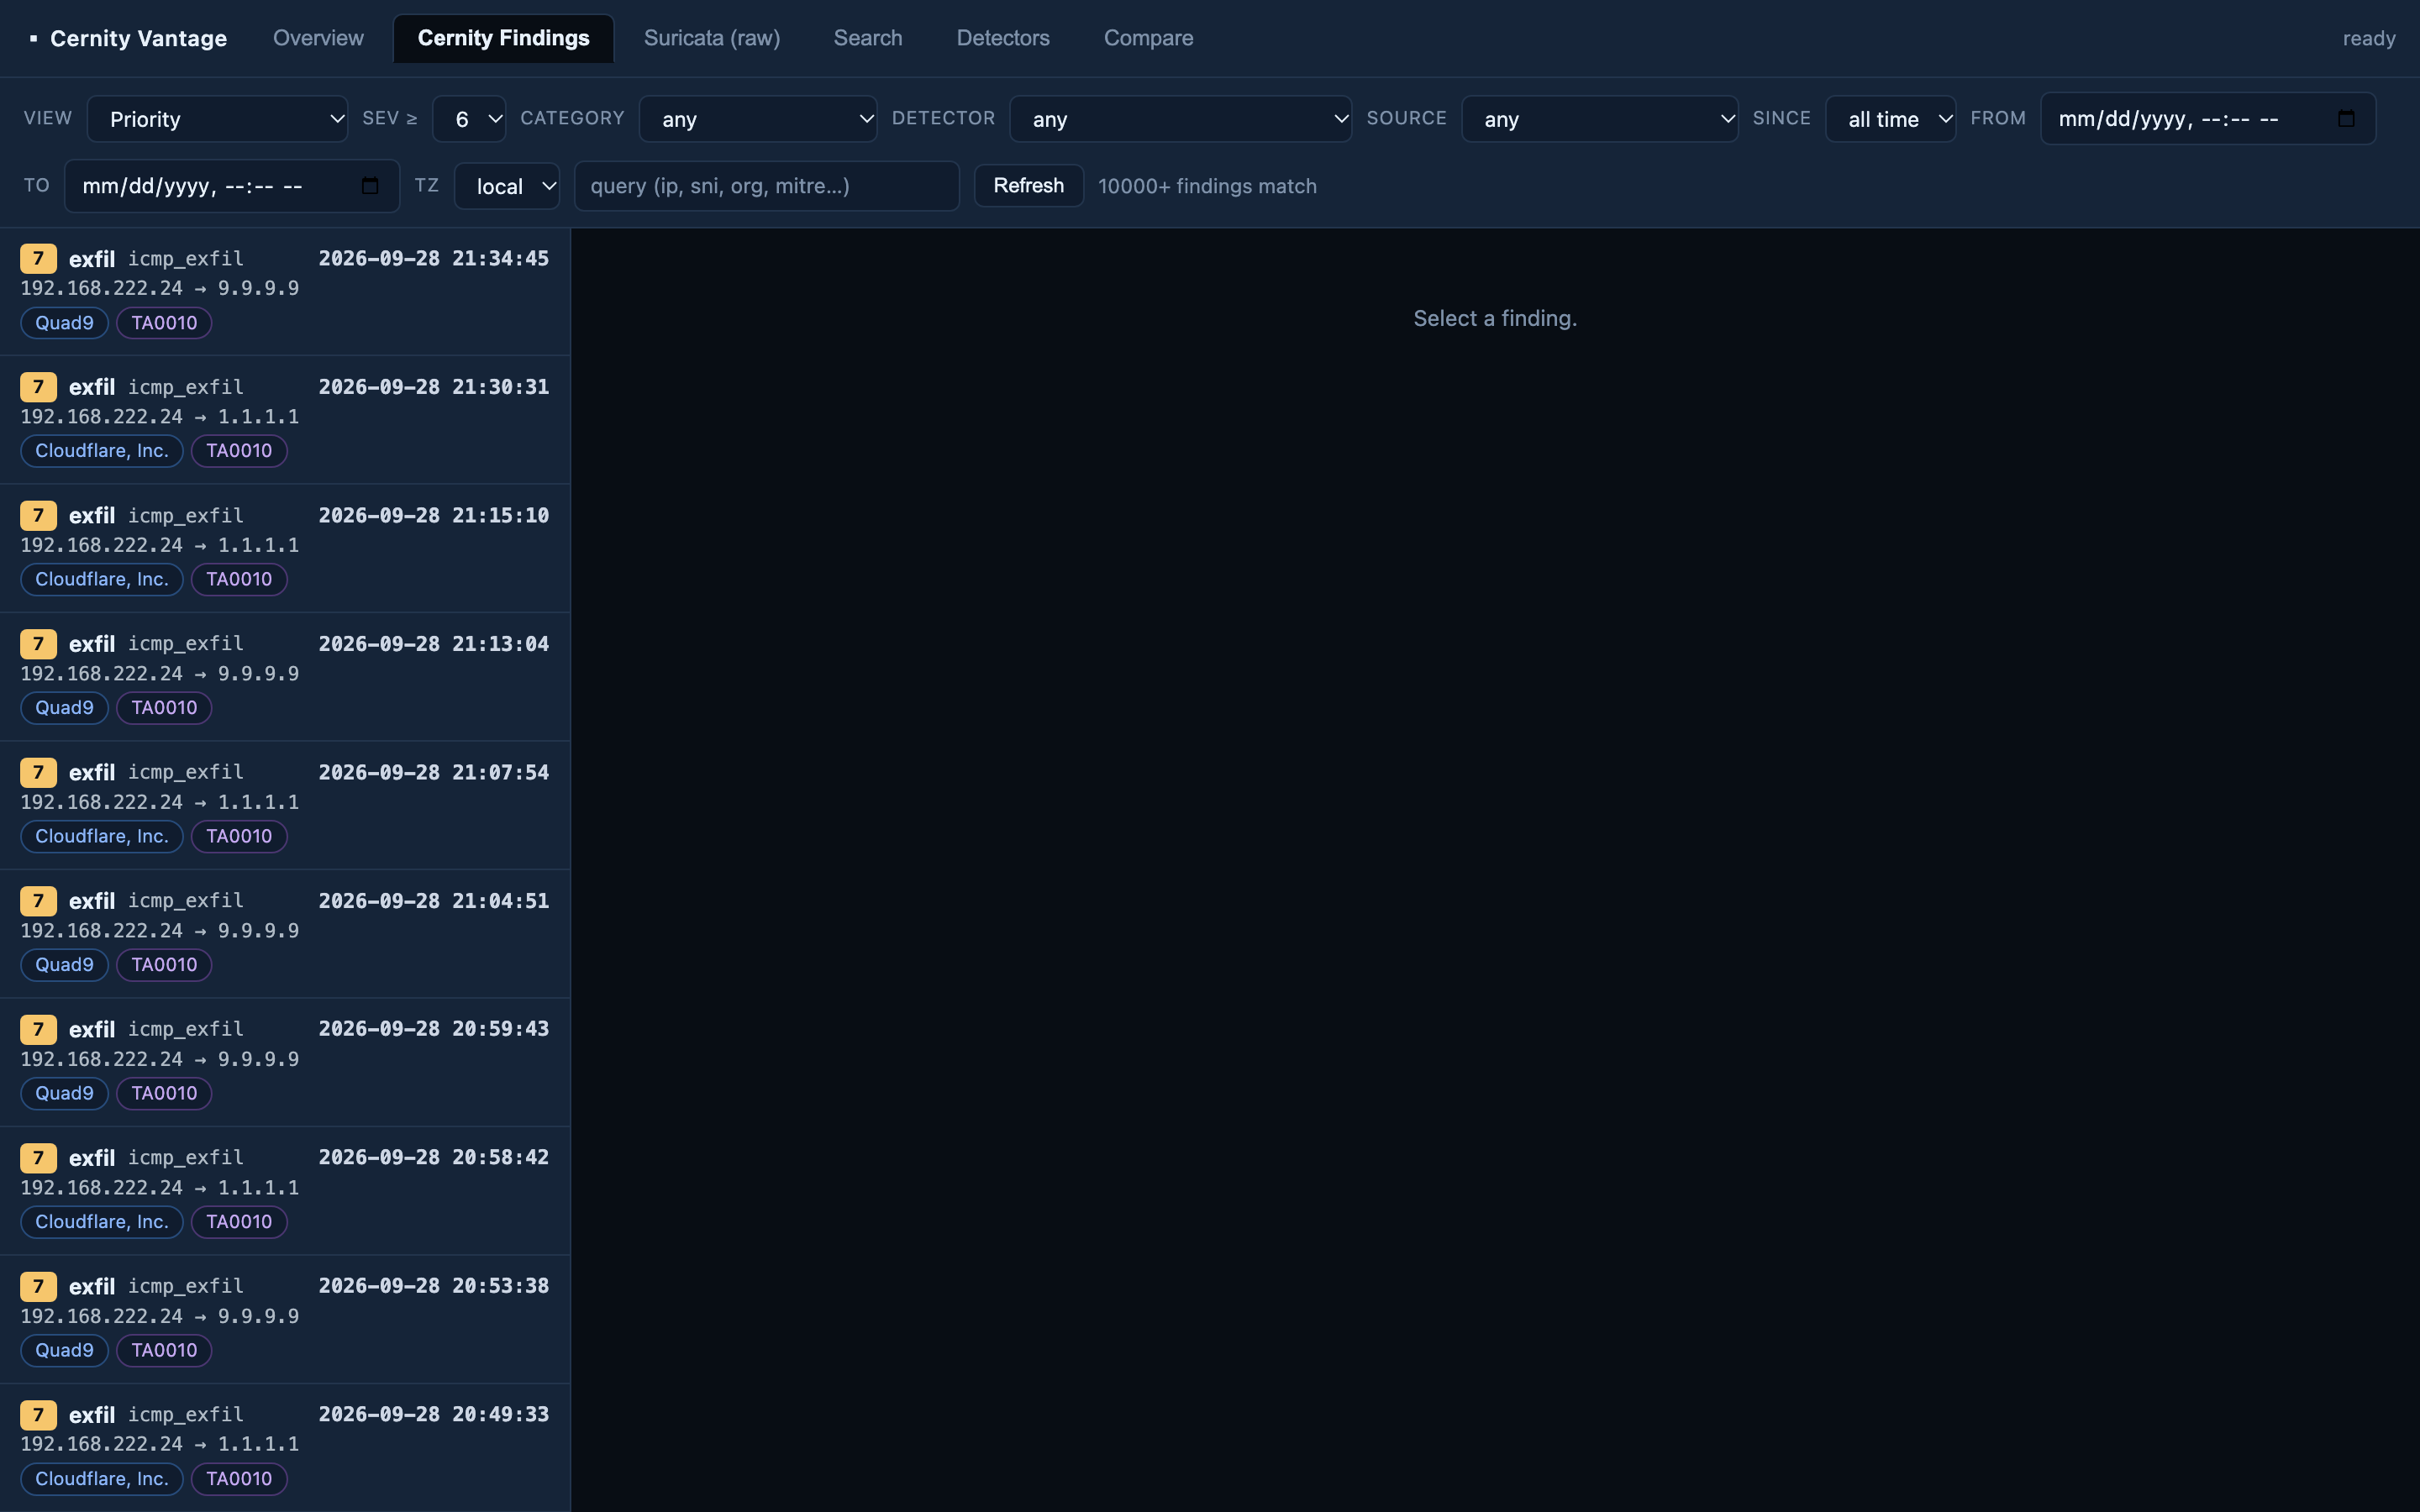
Vantage is built around an investigation queue with explicit triage tiers. The tiers are lead-ordering aids: they rank what to look at first so high-signal work stays at the top and low-signal noise never crowds it out. A tier is not a verdict or a confirmation — the “threat” tier does not establish that something is a threat, only that it should be looked at first. The investigation, not the tier, establishes what happened.
| Tier | How to read it — an ordering aid, never a verdict |
|---|---|
| Threat | Investigate first: the highest-priority lead, not a confirmed threat |
| Lead | Worth investigating, not yet established |
| Low-signal | Lower-priority lead; still requires investigation, kept out of the way |
| Observation | Context, not an alert |
| Allowlisted | Matched a benign allowlist entry; suppressed from the active queue |
A benign allowlist keeps known-good behavior out of the queue without deleting it — allowlisted activity is still recorded, just not surfaced as work.
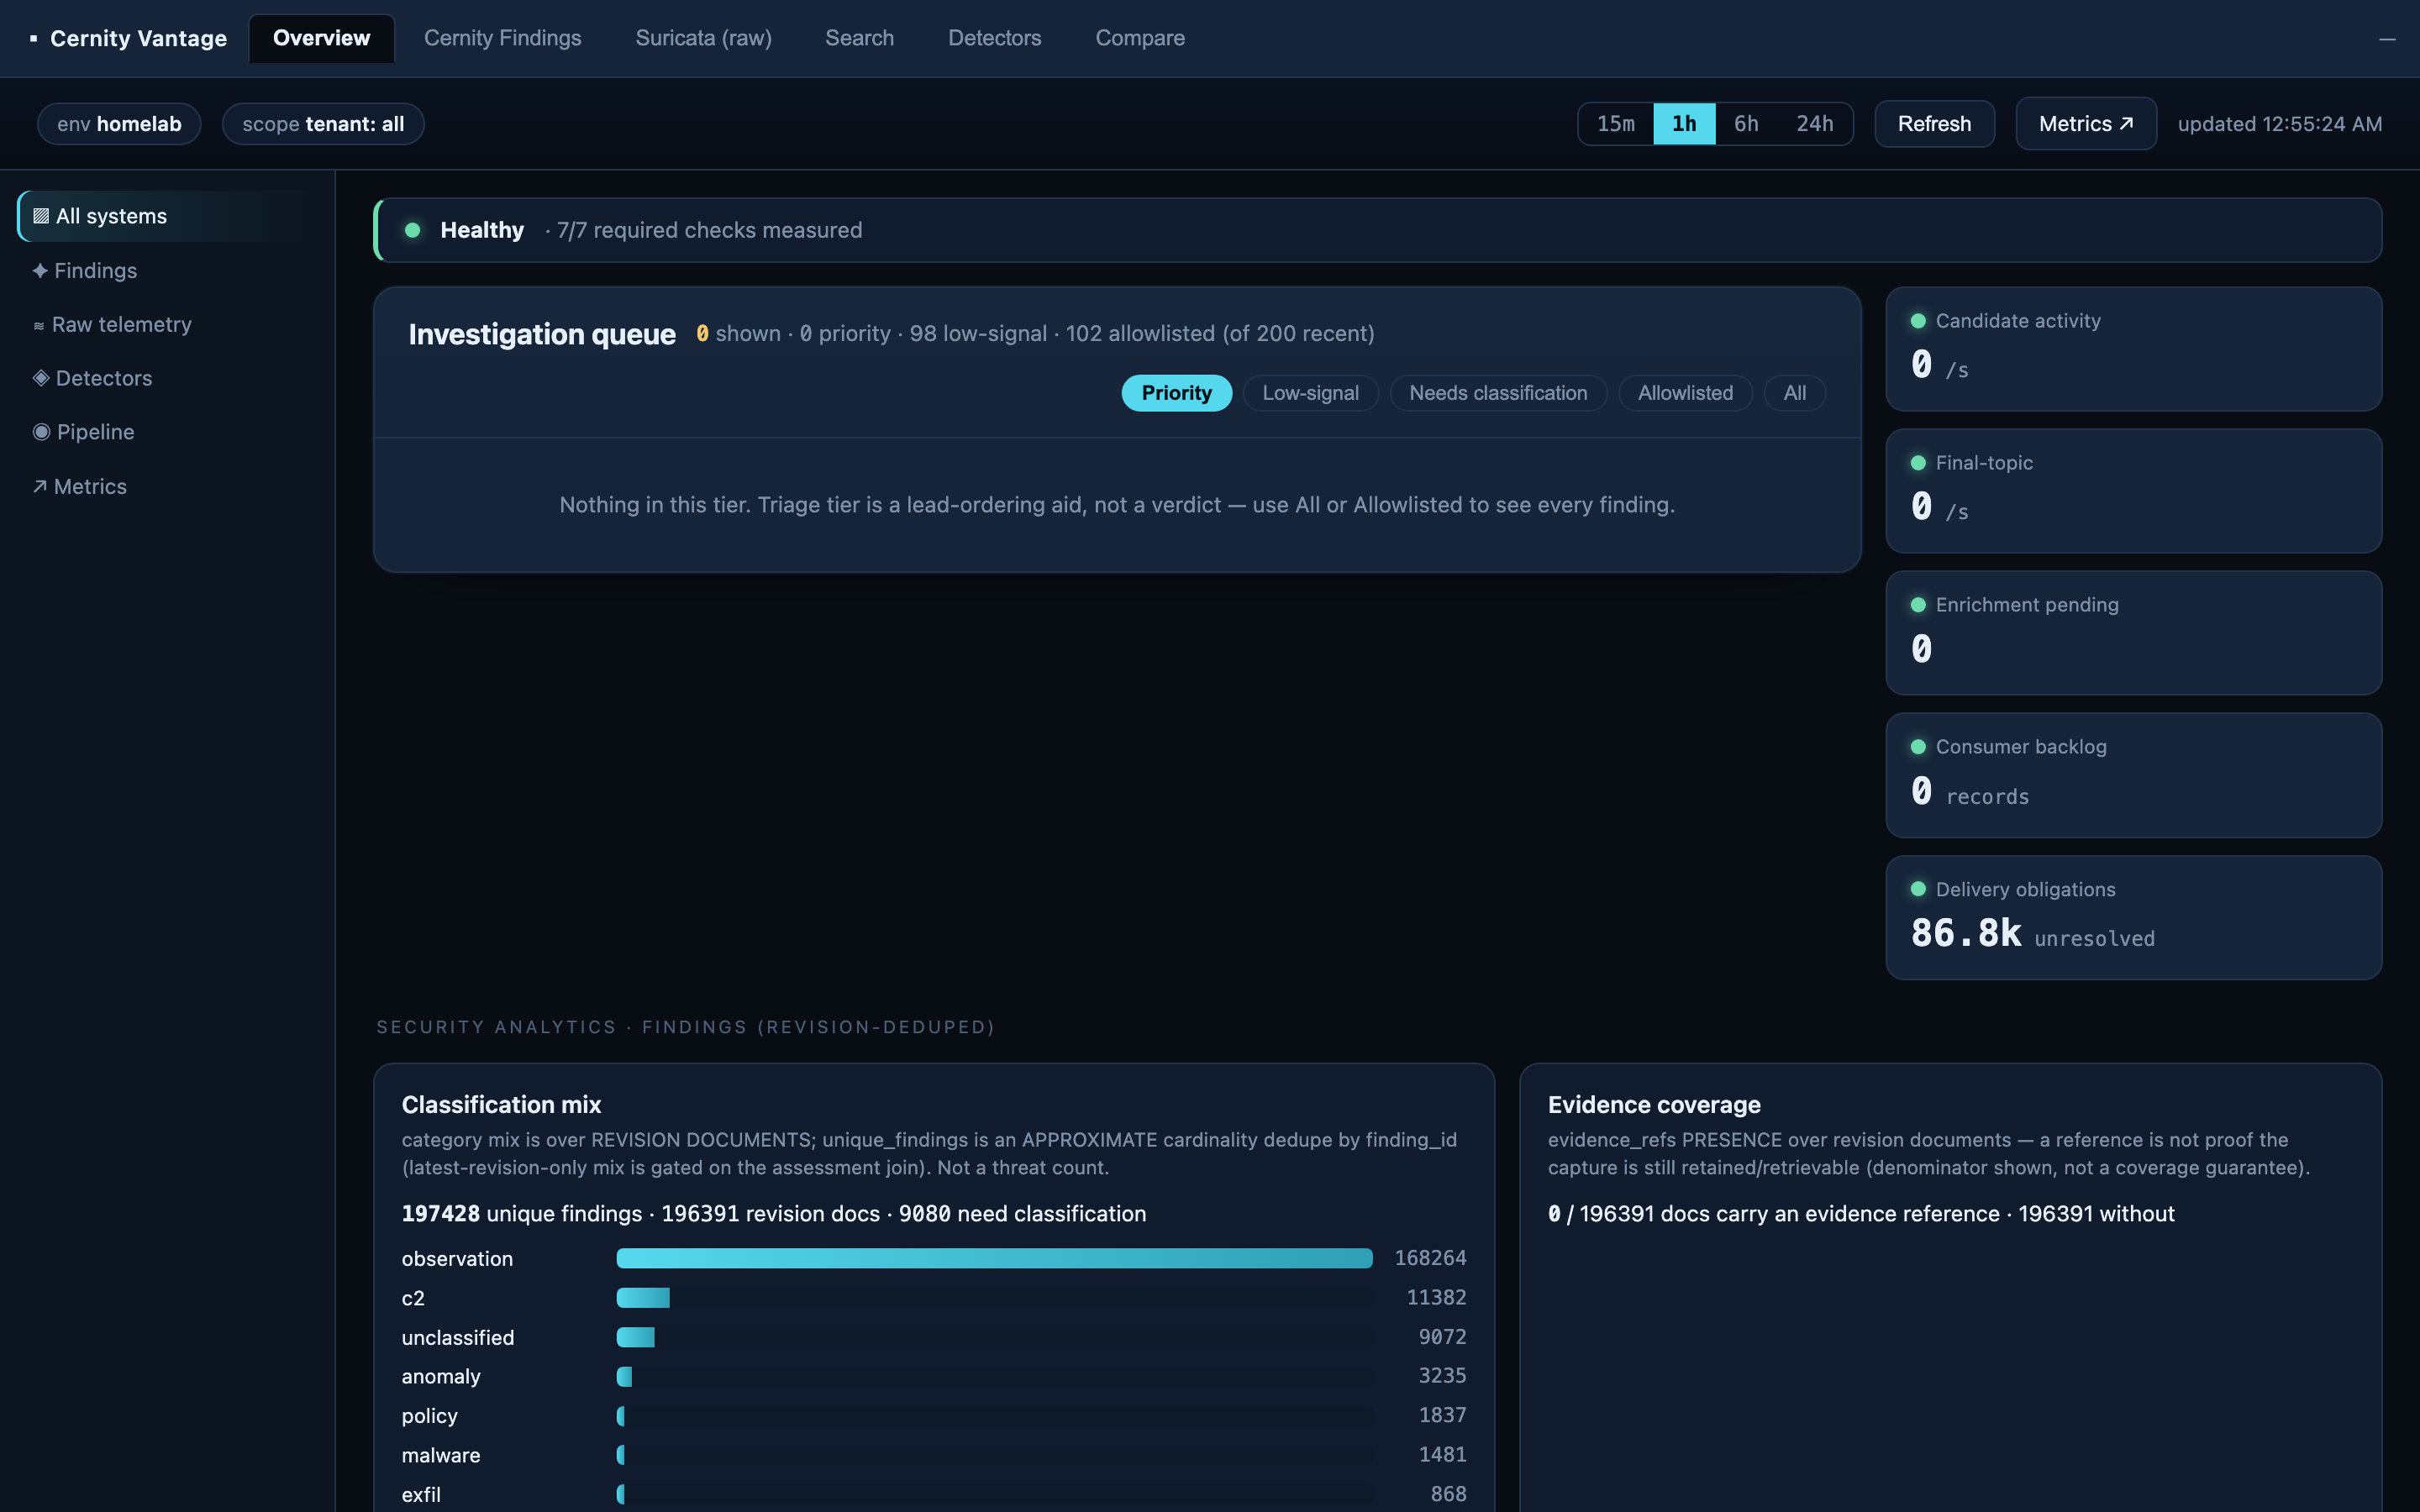
The Overview: is the pipeline healthy?
Before trusting a queue, an analyst needs to know the sensors feeding it are healthy. The Overview is a health and telemetry dashboard — ingest rates, finding volume, and pipeline state at a glance — so “the queue is quiet” can be distinguished from “a sensor went blind.”
The fleet-health view extends this to the sensor fleet itself — last-seen state, capture drops,
backlog, and clock skew drawn from sensor-health.v1 heartbeats. A finding from a sensor that
is dropping packets or whose clock has drifted carries a different weight, and the fleet-health view
makes that visible during triage. See fleet management.
The finding detail and the evidence pivot
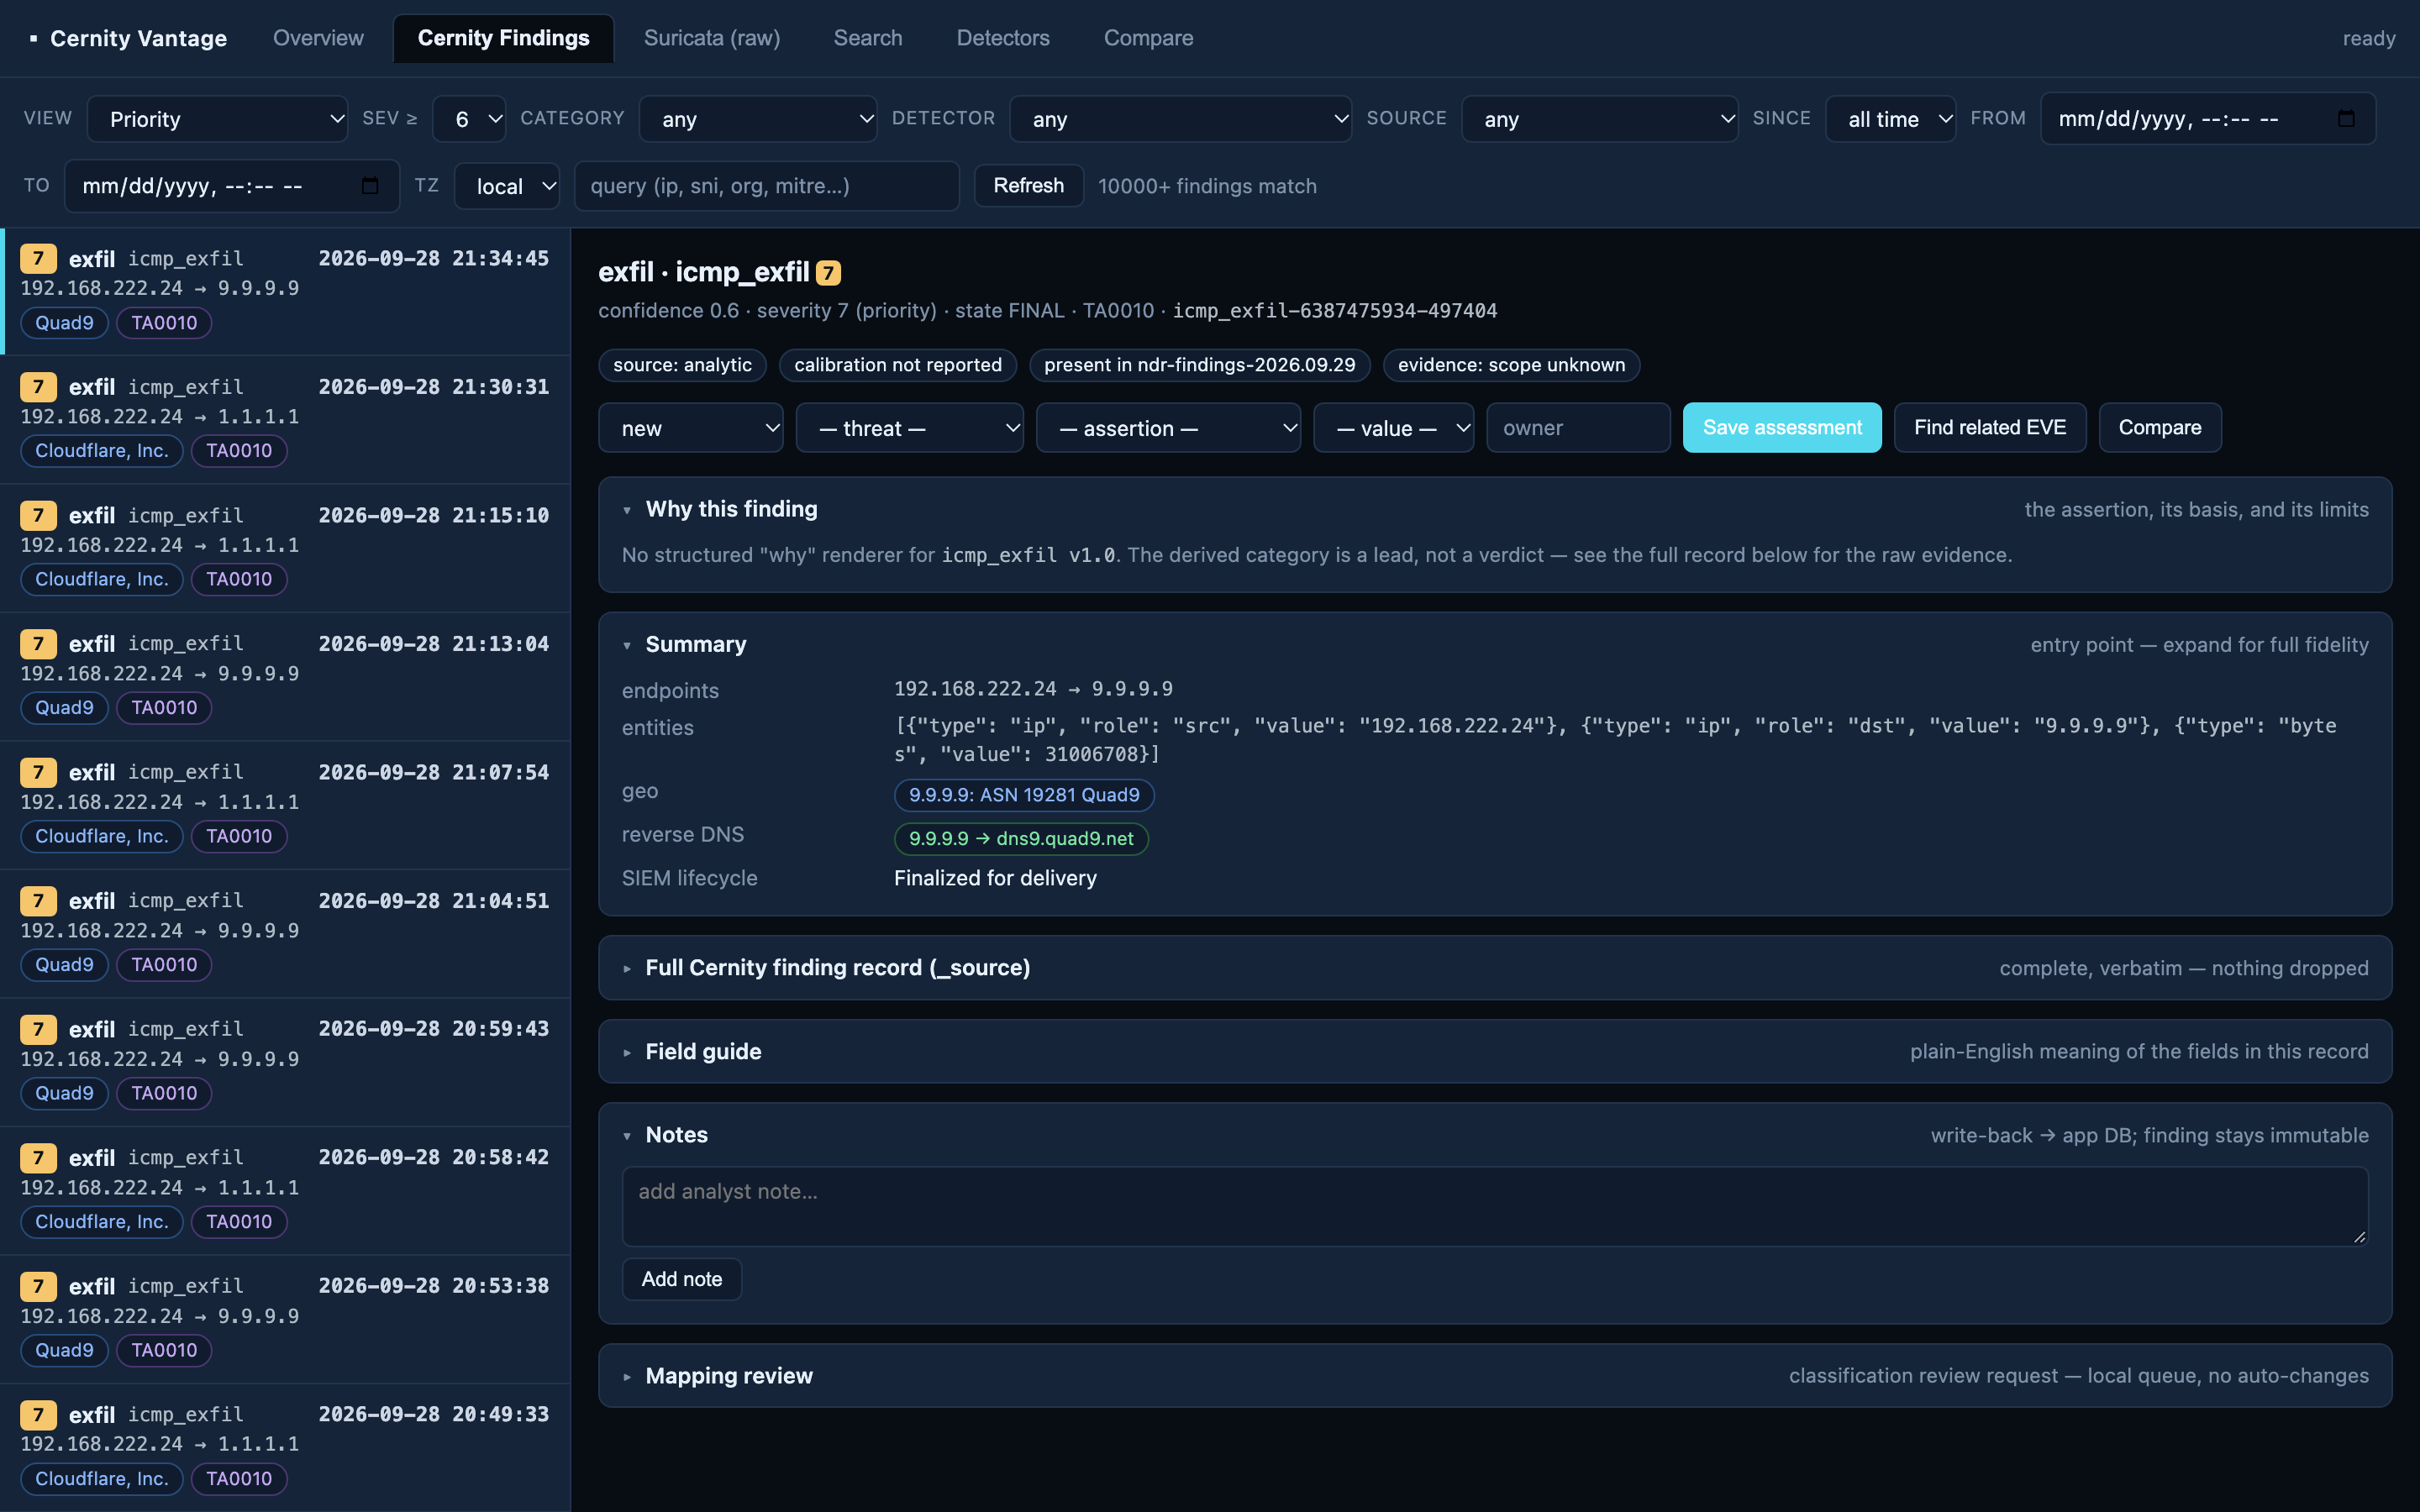
Open a finding and Vantage shows its detail — the finding’s confidence and severity, its lifecycle state, and a summary of endpoints, entities, geo and reverse-DNS enrichment, and SIEM lifecycle. Assessment controls let an analyst record a status, threat call, assertion, value, and owner and save that assessment against the finding. Where the finding is an anomaly, its explanation travels with it (features, both baselines, cohort, model and version); where a detector has no structured “why” renderer, Vantage says so and treats the derived category as a lead, not a verdict. From the detail, Find related EVE and the evidence-pivot view walk into the underlying normalized observations via the evidence query API — pulling the connection, DNS, TLS, or HTTP records for that entity, window, and type so you read the actual evidence. It is a filtered pivot into the underlying records, not a reconstruction of the exact records behind an aggregate count.
Case management
A single finding is rarely the whole story. Vantage lets analysts work an investigation as a case: a container that links multiple findings and entities into one unit of work. A case carries:
- Ownership and assignment — who is working it, so nothing sits unowned.
- A status lifecycle — new → investigating → resolved → closed — that says where the investigation actually is, distinct from any individual finding’s own lifecycle state.
- Analyst notes — the reasoning, corroboration, and decisions recorded alongside the linked evidence.
Cases are multi-analyst and fully audited: assignment changes, status transitions, notes, and link edits are all recorded, so who did what and when is always recoverable. The case is where the compact investigation record below actually lives.
Detection coverage and quality
Beyond individual findings, Vantage surfaces two views over detection itself, so an analyst can judge how much to trust a lead before opening it.
An ATT&CK coverage view maps detectors to MITRE ATT&CK techniques — which techniques have a detector, fleet-wide coverage, and per-tenant observed firings, with gaps highlighted. It answers “would we even see this technique?” before an incident, not after.
A production detection-quality view reports, per detector, a precision and false-positive rate derived from analyst dispositions, plus a separate advisory allowlist rate. Because it is computed from the tuning loop — the same dispositions analysts already record — a detector that has been firing false positives shows it, and a lead from a low-precision detector can be weighted accordingly. These are measured from your analysts’ own decisions; they describe a detector’s behavior in your deployment, not a promised detection rate. See detection coverage.
Separate observations from interpretation
The console gives you evidence; the discipline is yours. Write the supported observation first, and keep the working hypothesis separate so another analyst can challenge it.
| Observation you can report | Interpretation still needing evidence |
|---|---|
| Twenty connections show a measured five-second interval. | The host is communicating with command-and-control infrastructure. |
| One host contacted twelve internal destinations. | It successfully moved laterally into twelve machines. |
| Outbound bytes departed from both the entity and cohort baselines. | Sensitive data was stolen. |
| A rule with a specific SID matched. | The named malware successfully executed. |
| A fingerprint matches an operator-maintained label. | Only that named software could have created the connection. |
Verify coverage, then add context
Was the sensor watching the relevant segment? Did it see both directions? Were there drops or parser errors — and does the fleet-health view agree the sensor was healthy in that window? Then determine the asset owner, normal role, expected destinations, and change history, correlating with endpoint, authentication, and application logs. Cernity’s category cannot supply missing business authorization; the evidence pivot can supply the records that discriminate a benign explanation from an adverse one.
The tuning loop
A disposition in Vantage is not a dead end — it feeds back into the pipeline. Dispositions and
allowlist decisions are published as disposition.v1 and consumed by a feedback-service that
maintains three things:
- anomaly ground-truth — confirmed outcomes that inform future anomaly scoring,
- false-positive suppression — patterns an analyst has judged benign, and
- an ignore-list — activity to keep out of the queue.
Every entry is owner-attributed, justified, expiring, and audited, and the loop offers suggestions only — it never silently changes detection behavior. Tuning is therefore reviewable: you can always see who suppressed what, why, and until when.
Do not globally allowlist an address from a single synthetic case. Tune against validated deployment context, with a defined scope and an expiry so the effect on later detections stays visible.
A compact investigation record
For each case, retain: the observed behavior; the finding and its explanation; affected assets; the working hypothesis; the competing explanation; independent corroboration; visibility limitations (including sensor health for the window); the disposition and its basis; and any follow-up owner. Practice with the published records, which include real false leads and missing context. A detector’s label becomes one input to the investigation rather than its conclusion.